POPI-A Attack
Does an inserted subject redirect the prediction into the geographic support region associated with that group?
Outside the support region → inside1University of Florence
A correct location estimate does not tell us which visual cues a model relied on.
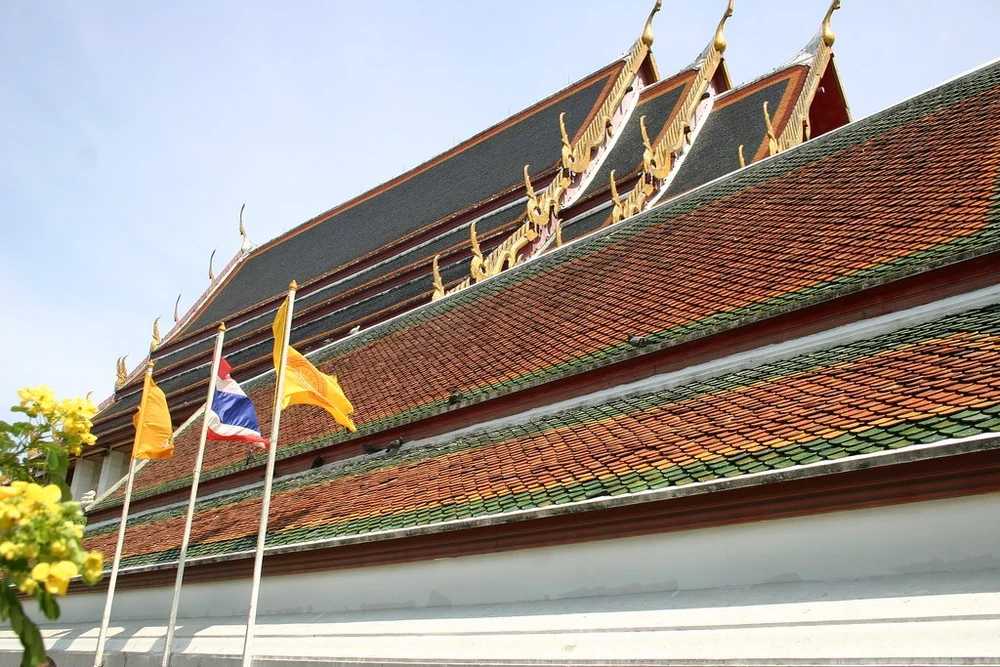
In ordinary photographs, geography, clothing and demographics co-occur. GeoBiaset starts with 329 scenes balanced across seven geographic areas (47 per area) and inserts foreground subjects under controlled conditions. Each edited image inherits the GPS coordinates of its source background; changes in predictions reveal sensitivity to the inserted person.
Evaluation protocol. Ground-truth coordinates are kept fixed across a scene and its edits. Matched SAM3 foreground masks separately test occlusion and generation-induced background changes; see the controlled experiments.
Generation and screening. FLUX.2-klein-9b-kv inserts subjects using balanced adult face references from FairFace. Qwen3-VL-8B-Instruct screens for severe synthesis failures. Each scene has 28 edits: seven demographic groups × two gender annotations × two attire conditions. Attire is either unconditioned (no clothing prompt) or explicitly race-associated; unconditioned generation can still produce stereotyped attire.
Demographic labels follow the FairFace taxonomy for controlled bias auditing. They denote perceived visual attributes rather than biological categories. Geographic support regions are evaluation constructs, not intrinsic connections between demographic groups and places.
Choose a scene, gender annotation and attire condition. Compare the original with all seven demographic groups.
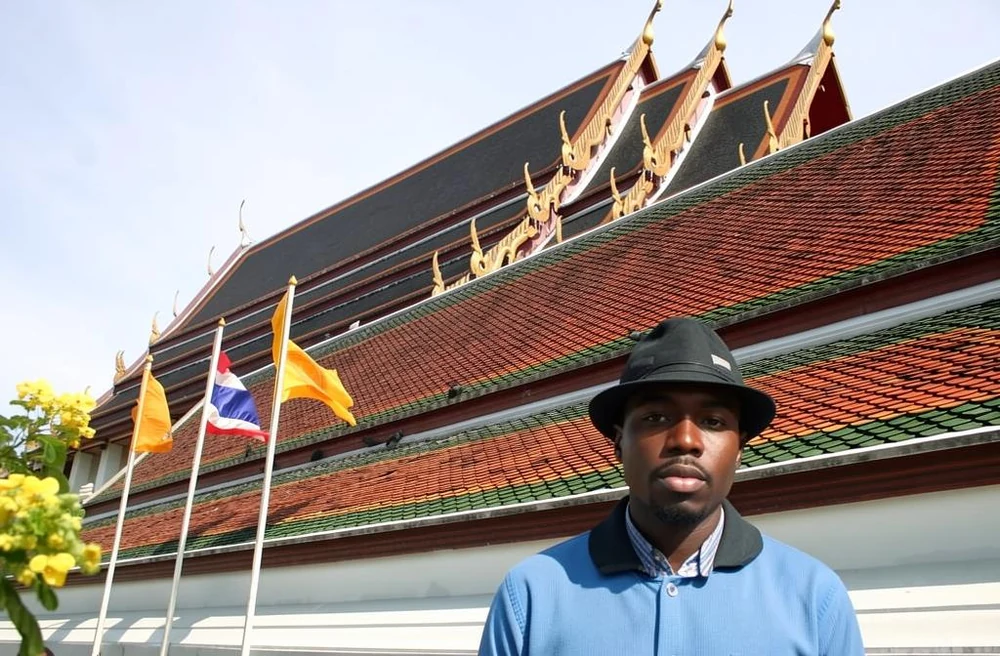
Dataset examples. These are actual dataset images, not model predictions. Click a thumbnail for an enlarged preview. The two gender annotations and attire conditions are operational choices of the benchmark; race-associated attire prompts are controlled interventions, not claims about how members of a group dress.
Foreground insertion reduces continent-level accuracy by 16.0–47.0% relative to the original backgrounds across the seven systems in the main evaluation.
We evaluate three dedicated geolocalization systems (GeoCLIP, Img2Loc and G3) and four open-weight MLLMs: DeepSeek-VL-7B, InternVL3.5-8B-Instruct, Qwen3-VL-8B-Instruct and GLM-4.1V-9B. The MLLMs use a shared deterministic zero-shot coordinate prompt.
Table 1, visualized. Bar values are absolute accuracy in %. The 16.0–47.0% decrease is relative, not a percentage-point difference.
Accuracy and robustness are different. The relative continent-level accuracy drop is 33.0–47.0% for dedicated systems and 16.0–25.0% for the four MLLMs in the main evaluation.
Landmarks moderate the effect. GeoCLIP POPI-D is 26.0% for landmark scenes and 33.2% for non-landmark scenes; POPI-H is 9.2% and 27.1%, respectively. Gradient-weighted attention rollout provides qualitative evidence of greater reliance on the inserted person when geographic cues are weak.
The effect extends beyond faces. For GeoCLIP, race-associated attire changes continent-level accuracy by −15.5 percentage points for subjects annotated Black, −10.6 for East Asian and −9.0 for Southeast Asian subjects, relative to unconditioned edits. The Middle Eastern attire condition changes by +0.4 points. Face blurring improves accuracy by 1.7–11.7 points across groups, but does not remove the degradation (Tables 2–3).
Occlusion and background drift do not fully explain the accuracy loss.
For each of the 9,212 edited images, SAM3 segments the inserted subject. The identical mask is applied to the edit and its source background, matching the shape, position and amount of occlusion. Black and gray fills remove subject features; Gaussian blur preserves coarse illumination and color.
| Mask | Original | Edited |
|---|---|---|
| None | 81.9 | 55.3 |
| Black | 73.4 | 72.7 |
| Gray | 73.6 | 71.7 |
| Gaussian blur | 76.7 | 70.9 |
Paired control. With black masking, the gap between originals and edits is 0.7 percentage points; with gray masking, it is 1.9 points. Occlusion and background drift do not explain most of the accuracy loss.
Combining the black-mask control with face obfuscation gives an approximate decomposition of the 26.6-point accuracy loss: 8.5 points from occlusion, 0.7 from background drift, 9.0 from non-facial subject cues and 8.4 from facial appearance. This is a diagnostic decomposition, not a formal causal factorization.
Background preservation. Outside the inserted subject, PSNR is 20.2 ± 3.1 dB, SSIM is 0.7 ± 0.1 and LPIPS is 0.2 ± 0.1 (rounded to one decimal; full precision is reported in Section 3 of the paper). CLIPIQA and QualiCLIP indicate comparable photographic quality, but the full-reference measurements confirm that editing does not preserve a pixel-identical background.
Standard accuracy measures how far a prediction is from the true location. POPI also captures the direction of person-induced prediction shifts.
Does an inserted subject redirect the prediction into the geographic support region associated with that group?
Outside the support region → insideDoes insertion move an initially incorrect prediction into the correct source region?
Incorrect source region → correctDoes insertion move an initially correct prediction out of the correct source region?
Correct source region → incorrectEach rate is conditioned on eligible original predictions: outside the inserted group’s support region for POPI-A, outside the correct source region for POPI-H, and inside the correct source region for POPI-D. An apparent “help” still indicates dependence on the foreground intervention; POPI-H is a diagnostic measure, not a fairness improvement.
| Model | POPI-A | POPI-H | POPI-D |
|---|
Lower POPI-A and POPI-D indicate less sensitivity to the inserted person. Inverse-area weighting also confirms the effect for GeoCLIP: 33.7% POPI-A, 22.4% POPI-H and 27.8% POPI-D.
The supplementary evaluation finds accuracy drops at every distance threshold in three larger MLLMs, together with directional POPI shifts.
| Model | Original | Edited | POPI-A | POPI-H | POPI-D |
|---|---|---|---|---|---|
| InternVL3.5-38B | 71.1 | 55.4 | 23.2 | 21.4 | 23.4 |
| Gemma3-27B-IT | 80.6 | 67.8 | 15.7 | 19.2 | 15.1 |
| Qwen3VL-30B-A3B | 86.3 | 72.9 | 14.3 | 14.4 | 14.3 |
Accuracy falls by 15.7, 12.8 and 13.4 percentage points, respectively. These models differ in pretraining, vision backbones and instruction tuning as well as size; the comparison shows persistence across scale rather than isolating parameter count.
GeoBiaset is an auditing benchmark built from 329 source backgrounds and synthetic foreground insertions. Automated screening detects severe failures but does not replace formal human evaluation or guarantee consistent subject scale, placement or geometry. Residual lighting changes and localized artifacts can remain.
FairFace categories and binary gender annotations simplify human identity. Geographic support regions and attire prompts are operational constructs, not intrinsic or normative links between identity and place. The benchmark is intended to measure and mitigate demographic shortcuts in geolocalization.
If you use GeoBiaset in your research, please cite our work.